Why Search Changes When the User Is an Agent ?
Still Searching Manually?
It’s a familiar scenario. Your team needs to evaluate LLMs for a new feature: Claude or GPT? You look up benchmarks online, and they contradict each other. Reddit threads dissolve into subjective arguments. Official docs highlight only selective strengths, and leaderboard rankings don’t align with your actual production experience. Four sources, four biases. So you cross-reference, filter out noise, fill in gaps. Two hours later, you’ve pieced together something that feels reasonable.
What were you actually doing? In effect, you were performing federated search by hand.
We tend to think of search as typing a query and getting results. But for complex questions, finding information is only the beginning. Traditional search focuses on retrieval; verification and judgment are left to the user. Humans are naturally good at assessing information quality. You know that a Reddit post and a peer-reviewed paper don't carry the same weight. You know certain sources have systematic biases. When the first page of results falls short, you rephrase your query, seek out more sources, cross-validate the information, and arrive at your own conclusion.
Hand the same task to an agent, though, a problem emerges: the agent's ability to judge information quality still depends heavily on the evidence the search system provides. If the system returns results from a single source, the agent gets an incomplete puzzle and then makes decisions based on that fragment. It's like forming a judgment from a single uncorroborated testimony: when the input itself is incomplete, no amount of downstream rigor can make the conclusion truly reliable.
When the user shifts from a human to an agent, search is no longer just an information entry point. It becomes a critical link in the reasoning chain. The problem is that traditional search was never designed for agents.
Three Assumptions That Break Down in the Agent Era
Traditional search rests on several default assumptions. When humans were the primary users of search, these assumptions mostly held. But when the user becomes an agent, they all start to break down.
Assumption 1: "A query fully expresses the user's intent"
When you search, you carry complete context implicitly. If you search for Apple earnings, you know you want Apple Inc.'s financial disclosures, not fruit market prices. The search engine doesn't need to understand your full background because all that context already lives in your head.
Agents also have rich context, yet it stays locked inside their reasoning chain. The search system never sees most of it. What the search engine ultimately receives is a compressed string stripped of original user intent. The result: the query an agent actually sends often captures only a fraction of the original task. The search system can understand the query, but not necessarily the true intent.
Assumption 2: "A single index is sufficient"
For human users, a general-purpose search engine is indeed enough. Looking up a concept, finding an article or checking the news-broad general coverage matches these needs perfectly.
But agents execute complex, specialized tasks. Monitoring markets requires real-time feeds from financial data sources. Tracing research threads demands citation graphs from scholarly indexes. Analyzing security vulnerabilities calls for structured queries against CVE databases. Each of these vertical data sources has its own data schema, query syntax, and update cadence. General-purpose search engines only scratch the surface. For agents, cross-source retrieval and information fusion can no longer be optional capabilities; they must be part of the search process itself.
Assumption 3: "The user will make the final judgment"
Ten blue links are the classic form of web search: the system returns candidates, and the human handles filtering, verification, and synthesis.
But an agent isn't the end consumer of search results. Search results are just one step in the reasoning chain. For an agent, results serve as input evidence for downstream reasoning, not reference material for browsing. Returning a ranked list of links is no longer enough. The search system needs to deliver information that is parseable, traceable, and verifiable. Search's role shifts accordingly: not returning results, but delivering evidence.
Tradeoffs and Design Decisions
Traditional search works for humans precisely because humans actively fill in context, seek additional sources, and evaluate result quality on their own. When the user becomes an agent, this work can no longer be left to the user. It has to become part of the search system itself.
This is the starting point for several of AnySearch's core architectural decisions: making the search system responsible not just for retrieving information, but also for understanding intent, coordinating sources, and controlling quality.
Here is how a query flows through AnySearch before it reaches the agent:
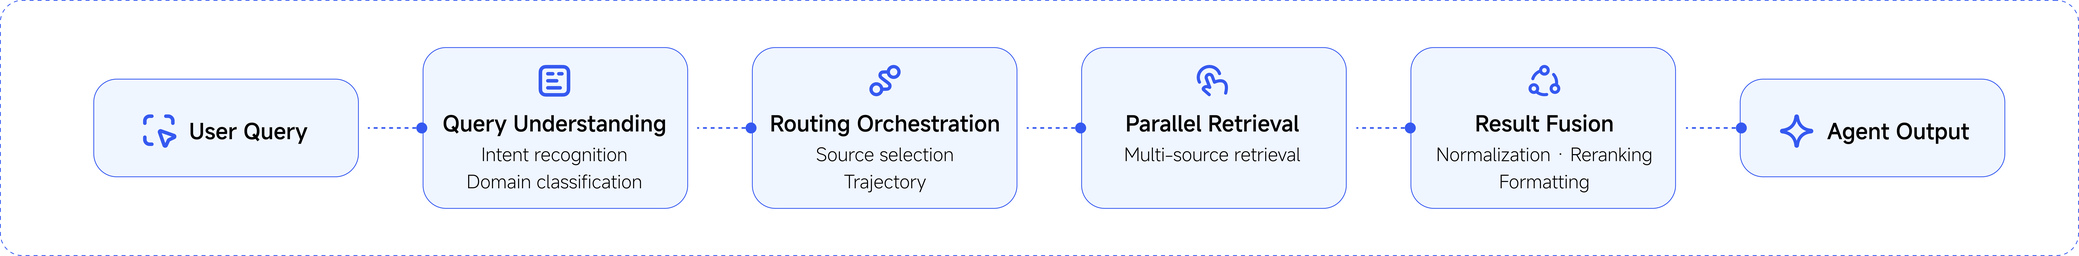
Mapping back to the three broken assumptions, AnySearch's design addresses three questions: how to understand an agent's true intent, how to retrieve information from multiple data sources, and how to take responsibility for the quality of all delivered data. The rest of this post walks through those design choices.
Decision 1: Query Understanding Drives Intelligent Routing
The first problem a query hits after entering the search system: with dozens of data sources available, which ones should it be sent to?
The most naive approach is full fan-out: broadcast to every source, then filter when results come back. The cost goes beyond latency. You're burning compute and bandwidth on irrelevant sources while flooding the fusion layer with low-value results, increasing the processing burden across the entire system. Even with in-house data sources, differences in index size, retrieval paths, and update frequency mean overall response time gets bottlenecked by the slowest source.
AnySearch's approach is to insert a query understanding layer before routing: analyze intent and domain, generate routing signals, then match these against what each data source is best at. A query like "Claude vs GPT function calling reliability" would hit tech blogs, developer forums, and benchmark datasets—skipping news, e-commerce, and academic papers. It's not that those sources are worthless; they're simply not valuable for this particular query.
Fan-out evolves from indiscriminate broadcast to intent-aware dispatch. Resources concentrate on higher-value retrieval paths, and the fusion layer downstream faces a cleaner, more manageable result set.
The tradeoff: There is always a precision-recall tension here. Tighter routing means faster responses, but it also raises the risk of missing something unexpectedly relevant. There's no permanent solution to this, only continuous experimentation and tuning.
Decision 2: Federated Architecture Drives Multi-Source Retrieval
Given that a single source isn't enough, there are two paths: either build one massive index that ingests as much information as possible into a single system, or build deep, domain-specific indexes in high-value verticals and use general-purpose search to cover the long tail.
AnySearch chose the latter. The scale advantage of a general web index took decades of infrastructure investment and enormous capital to build. Competing on that axis is a game of scale. But in verticals like finance, legal, academic, code, and security, deep indexes can far exceed what general-purpose engines achieve through broad-coverage scanning, both in data quality and retrieval precision.
General-purpose indexes optimize for breadth of coverage. Vertical indexes optimize for depth within a domain.
Federated search isn't API aggregation—it's selecting high-quality results from each relevant vertical domain and producing a unified answer through a fusion layer.
A single query might simultaneously need code search, a vulnerability database, and developer community discussions. No single index can be the best across all three dimensions, but a federated architecture can combine each source's strongest output.
The tradeoff: On top of indexing and ranking, the system adds an entire layer of scheduling and orchestration complexity. Routing decisions, parallel fan-out, cross-source result fusion, agent-oriented ranking algorithms—all become first-class concerns in a federated architecture. Data sources are naturally distributed across the globe; multi-region deployment is a fundamental prerequisite, not an optimization.
Decision 3: Continuously Building In-House Data Pipelines to Control Quality
Even after solving intent understanding and multi-source retrieval, the quality of evidence ultimately delivered to an agent still depends on the underlying data itself. Relying entirely on third-party APIs means ceding control over data quality, update frequency, and service availability.
That's why AnySearch has been continuously refining its in-house data pipeline architecture from day one: the end-to-end chain from crawling to cleaning to index construction. Core high-demand verticals are continually expanded with self-built indexes, with full control over data quality, update cadence, and retrieval strategies. General-purpose search still supplements the long tail, but we must maintain direct control over data in high-value domains—because no matter how sophisticated the runtime orchestration, it cannot overcome the limits of the underlying data.
We build progressively, prioritized by domain. Each additional vertical we cover is one more degree of control the system gains.
The core challenge of federated search was never "can we find it"; it was always "can we orchestrate and fuse it well". Every query has a different optimal execution path, and the search system must figure that out in real time.
Open Problems
Even so, we believe agent search is still in its very early stages. Several fundamental problems have no standard answers today.
Without Ground Truth, How Does the System Learn?
Traditional search has a click-through rate as an implicit feedback signal. Agent search doesn't. The search system has no visibility into what the agent does with the results, how the reasoning performs, or the quality of the final decision. This is a classic open-loop system: the search system generates output but receives no quality feedback.
AnySearch currently uses multi-dimensional indirect signals—source authority, content relevance, data freshness—to compute composite scores. But these are all proxy metrics. The fundamental question remains unresolved: how do you build a feedback loop from agents? How do you collect effective signals while respecting user privacy?
Why Is Semantic Caching Harder Than It Sounds?
Search caching is far from simple key-value matching. Should queries like "iPhone 17 评测" and "iPhone 17 review" hit the same cache entry? Data freshness requirements vary drastically across domains: financial data may expire in minutes, while legal precedents may remain valid for years. When a query partially hits and partially misses the cache, should the system wait for a full refresh or return partial results first?
AnySearch addresses these scenarios with query normalization, per-source differentiated TTLs, and partial-hit blended responses. But frankly, cache hit rates are still far from where we want them. The core difficulty is this: semantic similarity is continuous, but caching decisions are discrete.
How Do You Unify Scoring Across Domains?
Multiple vertical sources return candidate results, but their scoring systems are entirely different: news ranks by recency, academic papers by citation count, code by GitHub stars. These scores can't be directly compared on the same scale.
Can cross-domain "relevance" even be evaluated on a common scale? AnySearch's approach is two-stage: statistical methods for coarse ranking within a domain, then a semantic model for fine-grained re-ranking across domains. But striking the optimal balance between result quality and query speed remains a core engineering challenge.
Closing Thoughts
An increasing share of information retrieval, analysis, and decision-making is being carried out by agents.
When agents replace humans as the primary consumers of search, the responsibilities of search sysytem expand accordingly. Search is no longer just about returning results—it needs to take responsibility for the quality of information entering the reasoning chain.
Model capabilities will continue to improve. But as long as the information entry point deliver one-sided, outdated, and untraceable data, reasoning quality will always hit a ceiling. What truly needs to be rebuilt for the agent era is not just model capability, but the way information reaches the model.
That is the layer AnySearch is building: information infrastructure that connects agents to the real world.